Cachino
a go proxy between a coding agent and vLLM that predicts every prefix-cache hit and explains where agents lose reuse.
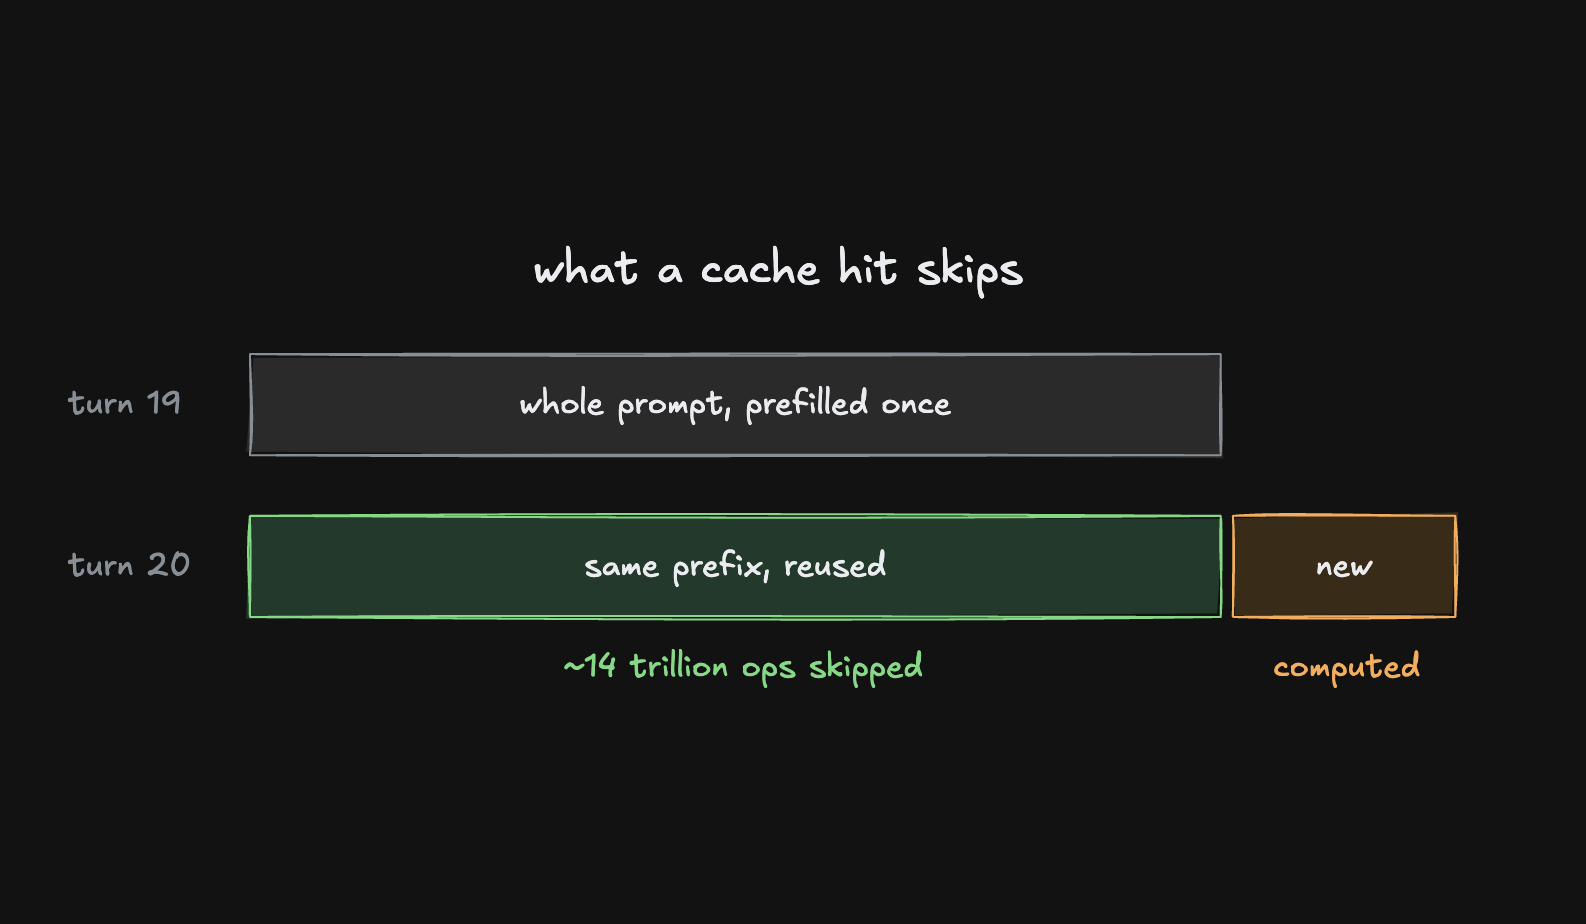
Coding agents resend their whole conversation every turn, so prefix caching should skip most of the work. When it doesn't, vLLM only tells you how many tokens were cached, not why the rest weren't. Cachino sits between the agent and vLLM, records every request byte for byte, and predicts each request's cache hit so every miss gets a cause: new content, a prompt that rendered differently, or eviction.
Related writing: i built a profiler to figure out why coding agents lose their prefix cache.
how it works
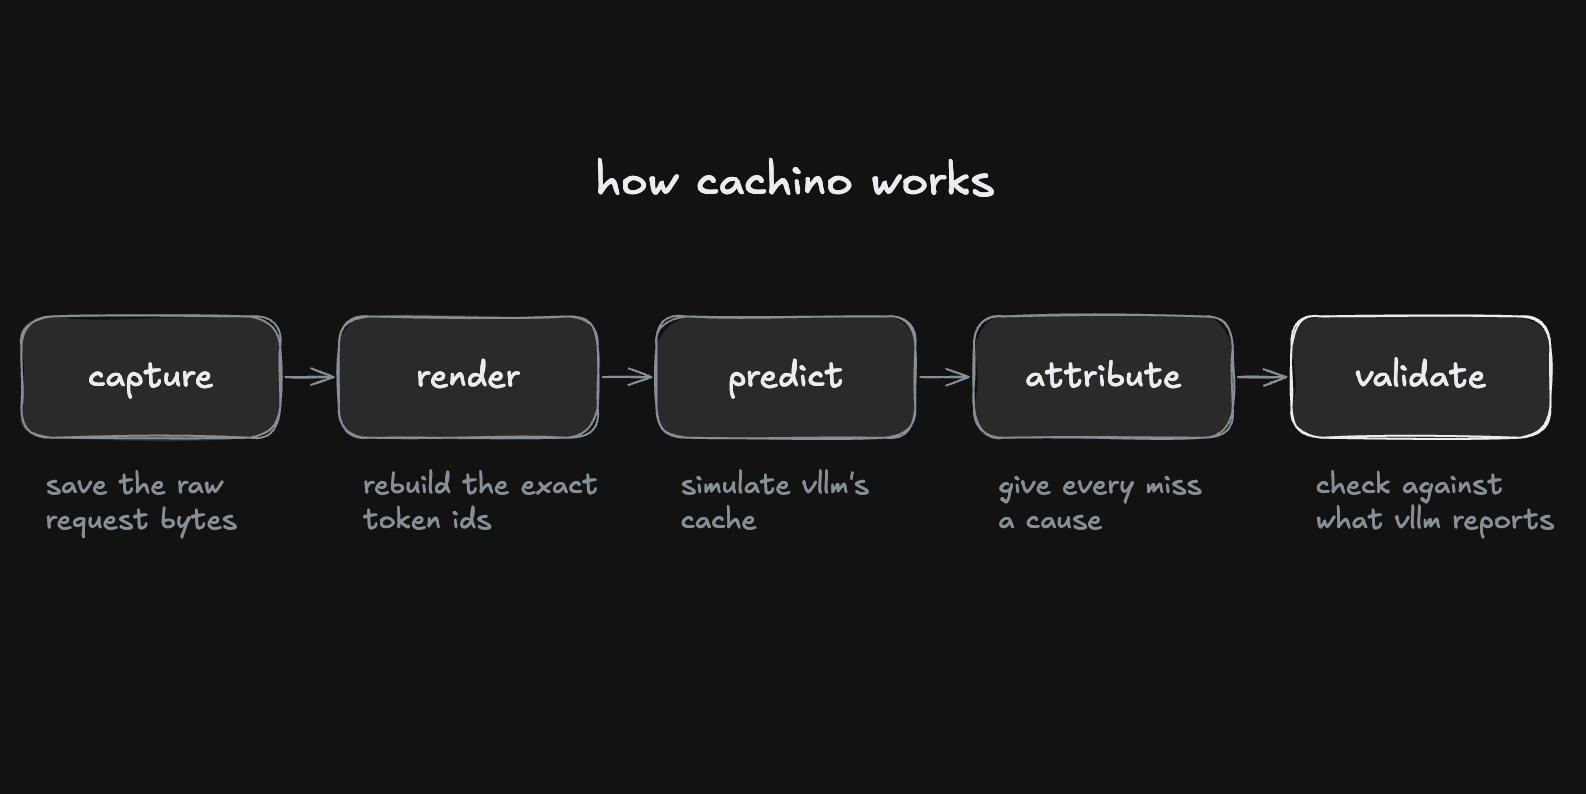
The proxy is plain Go, standard library only. The analysis rebuilds exact token IDs with a pinned tokenizer and models vLLM's prefix cache rule by rule, then checks every prediction against the engine. It matched every sequential replay and 710 of 738 requests under live concurrency.
what it found
- Qwen3's chat template re-prefills the last reply, because history drops the 4-token empty think block the model saw while generating.
- Harnesses can break reuse: smolagents rewrites each tool call with a random ID, so it never matches the cache.
- Eviction has a sharp threshold: one trace lost nothing at 488 blocks and exactly 32 tokens at 487, as predicted.
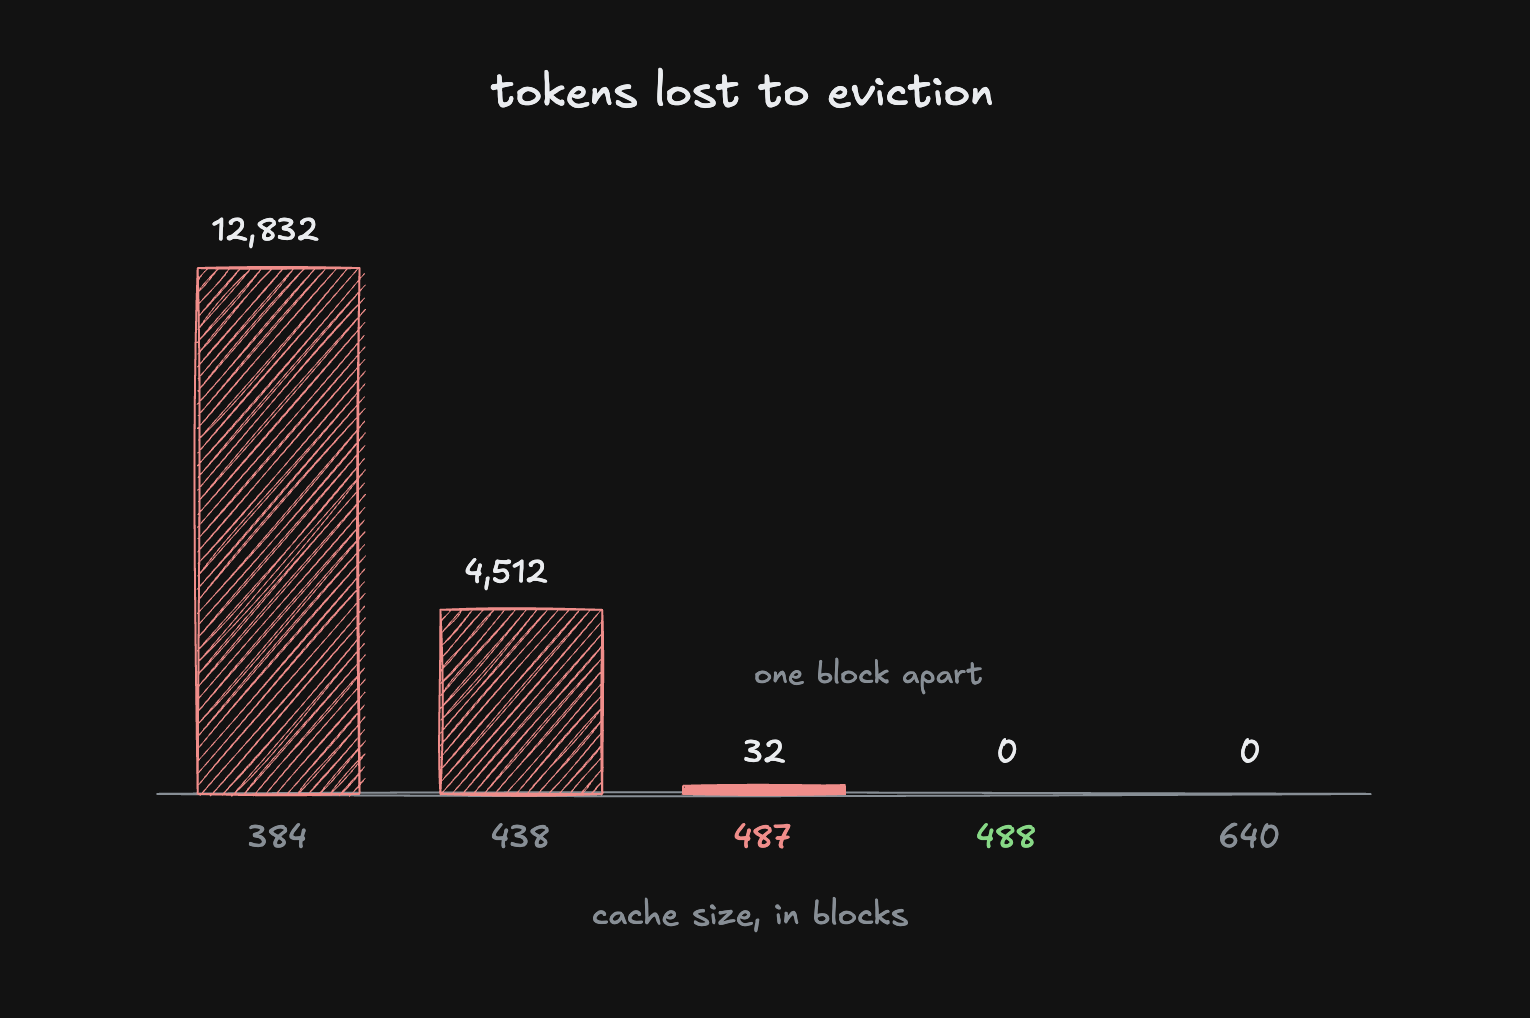
Measured on one task with Qwen3 0.6B and 1.7B. The full report has the method and limits.